Nabla Revisited: Designing Information Architecture for Humans and AI Agents
Revisiting an information architecture approach I first explored in 2019, and why I think it’s become more relevant in a world of interconnected applications, organisational knowledge and AI agents.
The problem with putting everything in its place
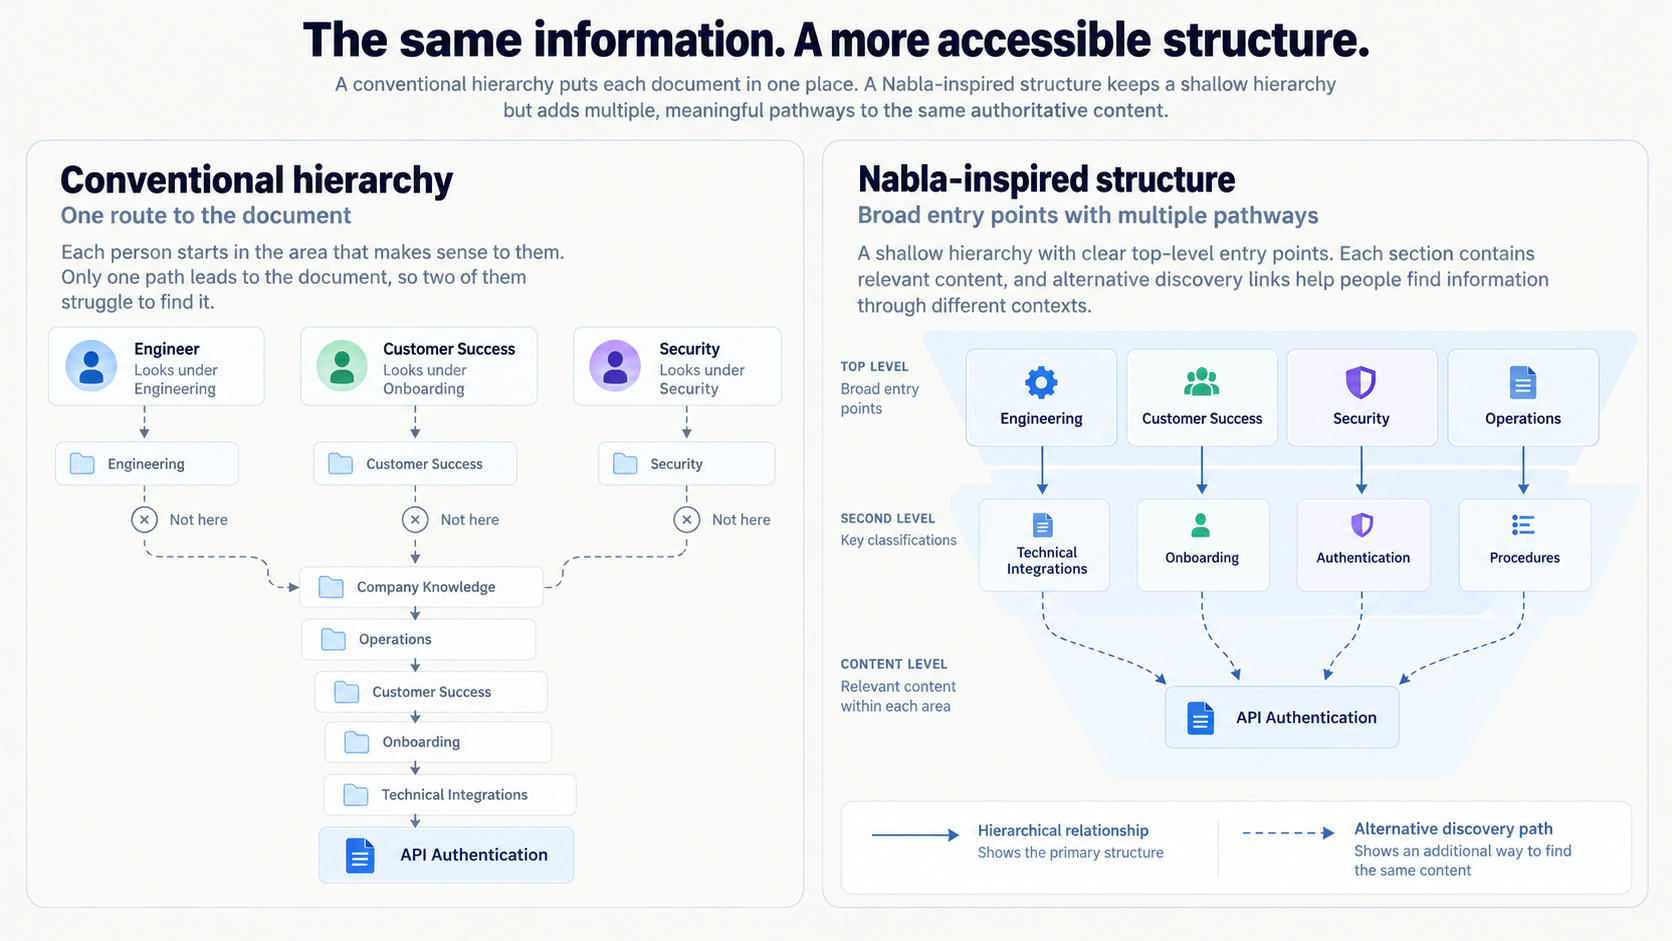
Imagine three people working for the same organisation, each trying to find the same document.
An engineer needs guidance on API authentication and starts looking under Engineering.
Someone in Customer Success needs the same information to onboard a client. They look under Onboarding.
A security specialist wants to review the authentication requirements and expects to find them under Security.
All three have perfectly reasonable expectations.
Unfortunately, the organisation has stored the document here:
- Company Knowledge
- Operations
- Customer Success
- Onboarding
- Technical Integrations
- API Authentication
- Technical Integrations
- Onboarding
- Customer Success
- Operations
The document exists. It’s organised logically, at least from the perspective of whoever created the folder structure.
Yet two of the three people looking for it might struggle to find it.
The problem isn’t necessarily poor organisation. It’s that the organisation has imposed one perspective on information that has several equally valid contexts.
Hierarchies are good at establishing where something belongs. They’re not always as good at helping people find something when they approach it from a different direction.
And the deeper those hierarchies become, the more finding information depends on understanding someone else’s organisational decisions.
Why should the way we organise information make that information unnecessarily difficult to find?
It’s a question I explored publicly in 2019, when I introduced an information architecture approach I called Nabla Site Structure.
At the time, I was primarily thinking about websites, navigation and search engine accessibility.
Seven years later, I’ve found myself revisiting the same ideas while developing a data-driven web application and experimenting with AI agents.
The problem hasn’t disappeared. If anything, the consequences of getting it wrong have become more interesting.
Revisiting Nabla
The name Nabla comes from the mathematical symbol ∇, an inverted triangle.
I thought it provided a useful visual representation of the approach I was describing.
Rather than forcing people through increasingly deep organisational structures, I wanted to explore an architecture that emphasised broad accessibility, meaningful classification and shorter paths to important information.
I wasn’t claiming to have invented shallow hierarchies or the underlying principles of information accessibility. Those ideas existed long before my original article.
I was interested in bringing several principles together, giving that combination a recognisable identity and applying it practically.
The original idea was straightforward:
Create a broad, accessible information structure that minimises unnecessary hierarchical depth while maintaining meaningful organisation and relationships.
Three principles sit behind that definition:
- Accessibility: Important information should be discoverable without requiring detailed knowledge of the system’s internal organisation.
- Meaningful classification: Information should be grouped according to useful relationships, not simply because a hierarchy requires another level.
- Multiple discovery pathways: Information relevant to several subjects or workflows should be discoverable through those different contexts.
None of this means everything should exist at the same level.
A folder containing 10,000 documents would technically be very shallow. It would also be a nightmare to navigate.
The objective is what I’d call the minimum useful hierarchy.
Sometimes that might mean two levels. Sometimes five. The important question is whether each level serves a genuine purpose.
Information has relationships, not just locations
Websites provide a useful example.
Consider a directory containing thousands of businesses, locations and individual services.
A conventional structure might organise everything geographically:
- United Kingdom
- England
- South West
- Devon
- Exeter
- Business
- Service
- Business
- Exeter
- Devon
- South West
- England
There’s nothing inherently wrong with this.
If geography is how most visitors approach the information, it may be entirely appropriate.
But what happens when someone wants to search by service type, price, availability or some combination of those characteristics?
Forcing every journey through geography means asking one hierarchy to solve several different discovery problems.
A more flexible approach separates the underlying information into meaningful entities: businesses, locations, services, categories and attributes.
Those entities have relationships.
A business operates at one or more locations. A location offers particular services. Those services have characteristics that make them relevant to different searches.
Once those relationships are represented properly, visitors can approach the same information from different directions.
One might start with a location. Another with a category. Someone else with a particular attribute.
They can all reach the same underlying offering without us maintaining several competing copies of it.
This is particularly relevant to a web application I’ve been developing recently.
One of the more interesting challenges hasn’t been deciding how information should appear on a page. It’s been structuring the information underneath it so that different views, filters and relationships remain accurate and maintainable.
A well-designed navigation menu cannot compensate for a confused data model.
Neither can a sophisticated search interface reliably compensate for inconsistent classification.
The architecture beneath the interface determines what kinds of discovery the interface can support.
And what about SEO?
My original article approached Nabla primarily through crawl accessibility, internal linking and website hierarchy.
Those considerations still matter, but I’d be more cautious today about claiming that shallow structures are better for all small websites.
Search engines don’t evaluate websites simply by counting clicks from the homepage. Internal linking, relevance, content quality, duplication and technical accessibility all contribute.
The more useful principle is that important information should have clear, logical and discoverable pathways appropriate to its purpose.
Once we separate that principle from SEO, the applications become considerably broader.
Ownership isn’t the same as discoverability
Businesses accumulate enormous quantities of information.
Policies, procedures, technical documentation, project plans, customer records, meeting notes and operational knowledge gradually spread across departments and applications.
Often, the problem isn’t that the information doesn’t exist.
It’s that nobody knows where to find the authoritative version.
Consider a company introducing a new customer onboarding process.
Engineering owns the technical integration guidance. Security maintains authentication policies. Customer Success manages the onboarding procedures.
Those responsibilities make sense.
But customer onboarding doesn’t happen neatly within one department.
Someone completing that process needs information from all three.
If discovery follows departmental ownership exclusively, they have to reconstruct those relationships themselves.
They need to know which teams are involved, where those teams store information and which documents are current.
The place where information is maintained doesn’t have to determine every way it can be discovered.
A shared onboarding entry point could reference the relevant documents while each department retains responsibility for maintaining its own information.
There’s no need to copy everything into another folder.
In fact, doing so might create more problems.
If three departments maintain separate copies of the same security policy, what happens when it changes?
Which version is authoritative? Who updates the others? How does someone recognise an obsolete copy?
Duplicating information to improve accessibility can undermine its reliability.
A better architecture connects authoritative sources to the different contexts in which they’re needed.
This principle applies beyond documentation.
A company might have one authoritative customer record used by several processes, or a product specification referenced by Engineering, Support and Marketing.
The challenge is making information available where it matters without creating competing versions of reality.
For people, that reduces frustration.
For systems that retrieve information automatically, the implications are potentially greater.
What changes when AI agents become information consumers?
Until recently, most of my thinking about information architecture revolved around human behaviour.
How does someone navigate a website? How do they understand a category structure? How does an employee find the information needed to complete a task?
Humans are remarkably resourceful when navigating poorly organised information.
If a document isn’t where we expect it, we try another search term. We might recognise that two documents describe the same thing using different terminology. We might ask a colleague.
AI agents can do some of these things too.
But we’re increasingly building environments where software doesn’t merely retrieve information for someone to read.
It retrieves information, interprets it, combines it with other sources and potentially uses the result to decide what happens next.
Imagine an AI coding agent preparing to modify an application.
It retrieves the technical specification, reads the README and examines previous architectural decisions.
Unfortunately, the documentation contains conflicting information.
An architectural decision is recorded in one Markdown file. An older README describes a different approach. A later discussion explains why the original design was abandoned, but nobody updated the other documents.
A human developer might investigate the contradiction.
An AI agent might do the same.
Or it might confidently implement a change based on obsolete requirements.
A poorly organised website might frustrate a visitor.
A poorly maintained knowledge system might lead an employee to follow an outdated procedure.
A poorly maintained agent-context system could lead software to act on incorrect assumptions.
The consequences become more significant when the systems consuming information can also act upon it.
That doesn’t mean AI agents are incapable of evaluating contradictory information. It means we should make that evaluation easier and more reliable.
And retrieving the correct document is only part of the problem.
The agent also needs to establish whether the information applies to its task, whether it has permission to act and how the outcome will be verified.
Good information architecture provides the foundation for reliable decisions. It doesn’t replace testing, evaluation or appropriate human oversight.
Designing context for agents
I’ve recently been experimenting with a small multi-agent working environment.
Different agents have responsibilities for research, development, strategy and other areas. To coordinate their work, I’ve been using shared context documents, current-state records and structured correspondence.
One recurring challenge has been deciding what information belongs where.
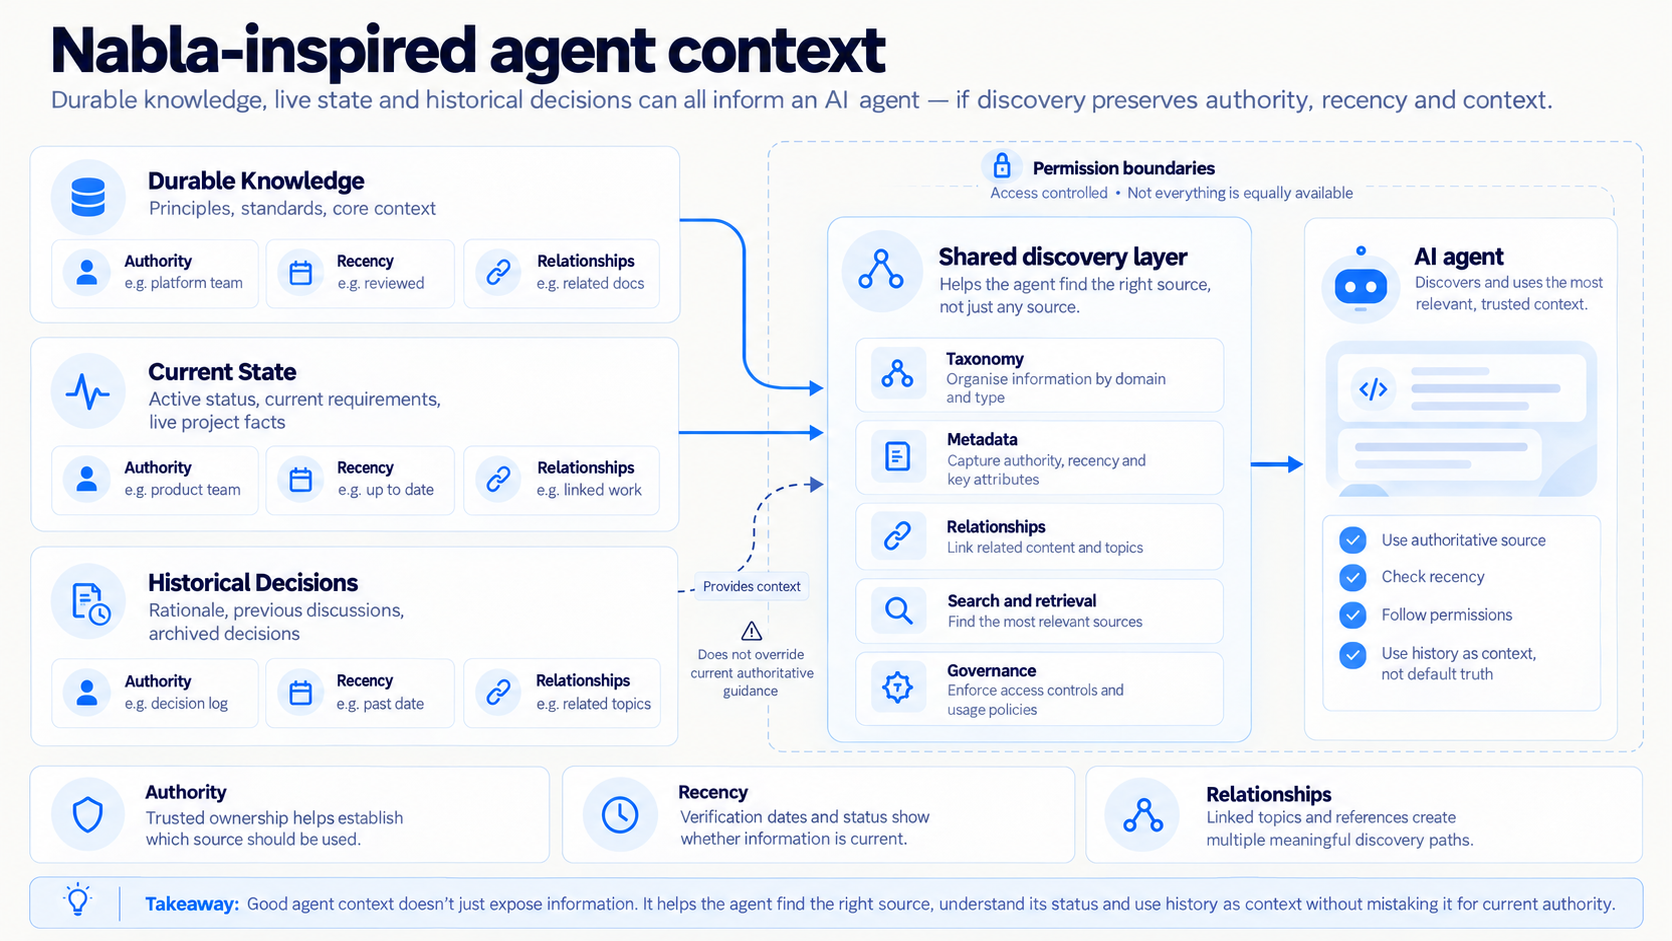
Some knowledge is durable.
A professional background, architectural principle or long-standing preference might remain relevant for months.
Other information changes frequently.
A project’s current status or an unresolved decision could become outdated tomorrow.
And some information exists primarily to explain the past.
It might record why a decision was made without necessarily describing what should happen next.
All three are useful, but they serve different purposes.
If they’re mixed indiscriminately into the same context, an agent may struggle to distinguish enduring guidance from temporary state or historical explanation.
A more deliberate Nabla structure might look like this:
- Shared Knowledge
- Core Context
- Current State
- Decisions and Rationale
- Project Documentation
- Agent Correspondence
This is still a hierarchy.
And that’s intentional.
The objective isn’t to replace folders with something supposedly more sophisticated.
It’s to help an agent discover the information relevant to its task and understand how the available sources relate to one another.
A current decision might reference a historical discussion. A development task might reference the authoritative repository. A research finding might include a verification date and links to its original sources.
Those relationships help establish not just where information exists, but how it should be interpreted.
A practical example
Consider a document containing API authentication guidance.
Rather than relying entirely on its folder location, we could give it a small amount of structured metadata:
id: api-authentication
title: API Authentication Guide
owner: engineering
status: current
verified_at: 2026-10-15

topics:
  - integrations
  - security
  - customer-onboarding

related:
  - onboarding-checklist
  - access-control-policy
Now the document has an authoritative owner, a lifecycle status, a verification date and several meaningful classifications.
An employee could discover it through an onboarding portal.
A developer could find it through technical documentation.
An AI agent could retrieve it using the relevant topics and relationships.
All three would reach the same underlying document.
Of course, metadata doesn’t maintain itself.
A verification date is only useful if someone actually verifies the information. A current status becomes misleading if nobody takes responsibility for updating it.
That’s why ownership and maintenance matter just as much as the structure.
From shallow hierarchies to meaningful information
This is where my interpretation of Nabla has evolved.
In 2019, I was primarily interested in reducing unnecessary navigational depth.
Today, I think the more interesting challenge is reducing the effort and uncertainty involved in finding the right information.
Hierarchy is only one part of that.
Taxonomy provides consistent classification. Metadata describes information assets. Relationships connect them across different contexts. Search and retrieval provide alternative access paths.
Governance establishes who maintains the information and how its reliability is preserved.
These mechanisms work together.
The API authentication document might belong to Engineering, be classified under Security and Integrations, and be referenced by Customer Success.
Different consumers can discover it in different ways while reaching the same authoritative source.
The question isn’t simply how shallow we can make the hierarchy.
It’s whether someone—or something—can find the correct information and establish that it’s appropriate to use.
Can they tell whether it’s current?
Can they distinguish a confirmed decision from an abandoned proposal?
Can they identify the authoritative source when two documents disagree?
Can they recognise when the available information isn’t sufficient?
Information architecture should make information easier to find, but also easier to trust appropriately.
That qualification matters.
Discoverability isn’t permission or truth
There’s a danger in taking the original Nabla concept too literally.
Not everything should be accessible to everyone.
Some information is confidential. Some belongs to a particular customer or department. Some requires specialised knowledge to interpret correctly.
And some information may be useful as historical context without being suitable as an instruction.
Making something easy to discover doesn’t make it accurate, trustworthy or appropriate to use.
An AI agent shouldn’t gain access to confidential information simply because it exists in a shared knowledge system.
Nor should it treat a retrieved document as authoritative merely because it appears relevant.
Access controls, ownership, versioning and review processes remain essential.
Sometimes that means retaining deeper hierarchies or separating information entirely.
Sometimes it means using relational models, knowledge graphs or specialised retrieval systems rather than conventional navigation.
Nabla shouldn’t become a rigid prescription that creates the very limitations it was intended to challenge.
The principle isn’t universal access.
It’s appropriate access to authoritative information with as little unnecessary friction as possible.
How I’d approach information architecture today
If I were designing an information architecture from scratch, I wouldn’t begin by drawing a folder hierarchy.
I’d begin with the work the system needs to support.
What are people trying to accomplish? What questions do they need answered? What information do they need to make decisions?
And where AI agents are involved, what actions might depend on the information they retrieve?
From there, I’d work through a practical process.
1. Identify the consumers and their tasks
Understand who needs information, what they’re trying to achieve and how they currently find what they need.
An employee, a developer and an AI agent may require different discovery paths to the same source.
2. Establish authoritative sources
Identify what information already exists, who owns it and which versions should be trusted.
There’s little value in creating elegant discovery pathways to unreliable information.
3. Design the minimum useful hierarchy
Create broad, meaningful entry points without introducing unnecessary levels.
Retain hierarchy where it improves comprehension, maintenance or security.
4. Add classification and relationships
Identify the topics, attributes and connections that reflect how information is actually used.
Support multiple discovery paths without creating unnecessary duplicate copies.
5. Define governance
Establish ownership, permissions, verification requirements and lifecycle rules.
Make current information distinguishable from proposals, historical records and deprecated guidance.
6. Test the architecture
This is the part I think is too often overlooked.
Don’t judge an information architecture solely by how logical its diagrams appear.
Give people and agents realistic tasks.
Ask an employee to find the current authentication requirements for a customer onboarding process.
Ask a developer to identify the architectural decision governing a particular component.
Ask an AI agent to retrieve the relevant requirements and explain which source takes precedence when documents disagree.
Then measure what happens.
Useful measures might include:
- Successful retrieval rate: How often the correct source is found.
- Time to authoritative information: How long it takes to locate something reliable.
- Stale-source retrieval rate: How frequently outdated material is selected.
- Conflict resolution: Whether consumers can identify which source takes precedence.
- Task completion accuracy: Whether the information supports the correct outcome.
Compare the results before and after architectural changes.
If a new structure looks cleaner but doesn’t improve how people or systems complete their work, what have we actually achieved?
And keep revisiting it.
Organisations change. Products evolve. Knowledge becomes outdated.
Information architecture should be treated as an ongoing, evidence-led process rather than a one-time exercise in arranging folders.
The principle hasn’t changed, but the applications have grown
When I first introduced Nabla Site Structure in 2019, I was primarily thinking about smaller websites.
For those sites, conventional hierarchies can introduce unnecessary complexity. An inverted-pyramid structure offers an alternative, keeping information broadly accessible without forcing visitors through multiple levels of categorisation.
I still believe it’s a useful approach in the right circumstances.
What’s changed over the last seven years is that I’ve started encountering similar architectural problems outside conventional websites.
Businesses organise knowledge into departmental folders. Developers maintain documentation across multiple repositories. AI agents need access to information that might be scattered across several systems.
These aren’t identical problems, and Nabla won’t necessarily be the appropriate solution to all of them.
But they raise many of the same questions I was asking in 2019.
How much hierarchy do we actually need? And is the structure helping people find and use information, or simply making it easier for us to organise?
That’s where I think the concept of a minimum useful hierarchy becomes particularly valuable.
Every additional level should have a reason to exist. It should improve classification, navigation, comprehension or maintenance. Otherwise, we should question whether it’s necessary.
For a small website, that might lead us towards Nabla.
For a larger organisation, it might mean retaining departmental ownership while creating shorter, cross-functional routes to important knowledge.
For AI agents, it might mean simplifying how documentation is organised and making the relationships between authoritative sources more explicit.
The solutions will differ, but the methodology is much the same: understand how information needs to be used, establish the relationships that matter, and introduce only the structure necessary to support those requirements.
Then test whether it works.
I think this is something businesses should be considering more seriously as they adopt AI and automation. Giving an agent access to thousands of documents is relatively straightforward. Ensuring it can consistently find the right information, in the right context, is another matter entirely.
Nabla is just one approach to information architecture worth considering. Its underlying principle of minimum useful hierarchy, however, should inform the design of any system that relies on hierarchical organisation.